db and the configuration as a view does.
At a glance
Environment variables
This guide adds one variable to the ones in Deploy a Flask application:Before you begin
- The
storefrontproject from Deploy Flask, deployed on Sevalla. This guide adds files to it and replaces itsapp/__init__.py.
Create a Redis database
1
Create the database
In the sidebar, click Databases, then click Create database. Under Database, choose Redis, or Valkey: the code in this guide works with both. Enter
storefront-redis as the Display name, choose the same Data center as the application and a Size, then click Create database.2
Connect it to the application
In the sidebar, click Applications, then click the application. Click the Networking tab. Under Connected services, click Add internal connection. Choose
storefront-redis as the Service, turn on Add environment variables to the application, and click Add internal connection. Sevalla adds REDIS_HOST, REDIS_PORT, REDIS_PASSWORD and REDIS_URL. See Connect an application.Add Celery to the project
In the project folder, with the virtual environment active, install Celery with its Redis support and updaterequirements.txt:
app/celery.py
app/tasks.py
app/__init__.py. It configures Celery with the Redis URL from the internal connection and adds a route that queues the task:
app/__init__.py
requirements.txt. The celery command loads it, which creates the Flask application and its Celery application:
make_celery.py
Run the worker on Sevalla
1
Create the background worker
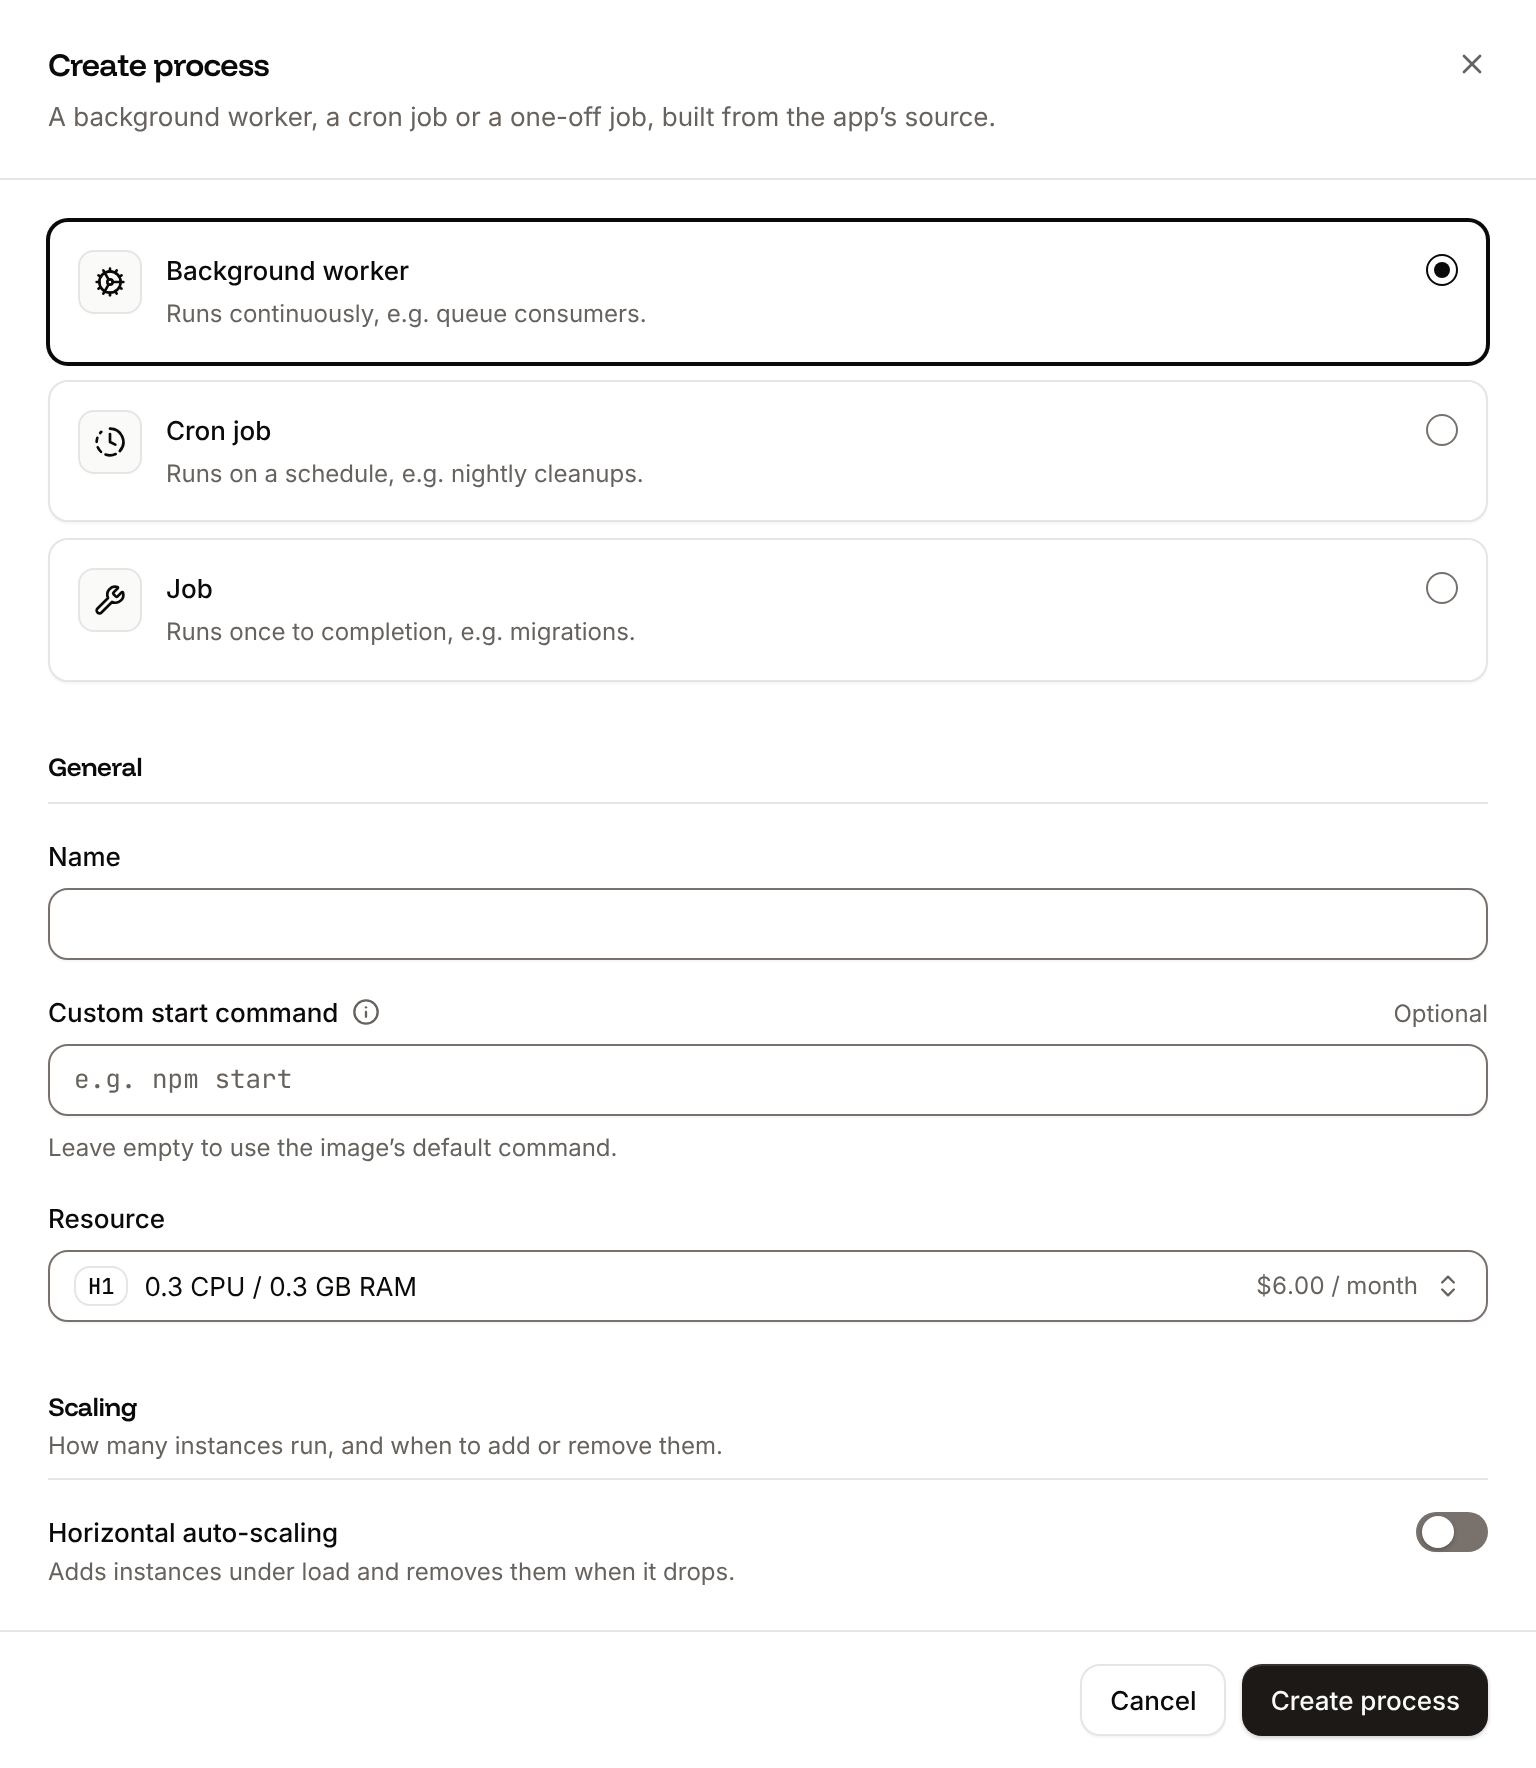
On the application’s Processes tab, click Create process. Choose Background worker, enter Keep the Resource at H1 or choose a larger one, and click Create process.
Celery worker as the Name and this Custom start command:2
Deploy
Click Deploy in the undeployed changes bar at the bottom of the page.
exec. Sevalla runs a custom start command with /bin/sh -l -c, and the shell, as the instance’s main process, doesn’t pass SIGTERM on. exec replaces the shell with Celery, so when an instance stops during a deployment, Celery gets the signal, finishes the tasks it’s running and logs worker: Warm shutdown (MainProcess). Without exec, Sevalla stops the worker 30 seconds later, in the middle of its tasks.
Set --concurrency to match the size. Without it, Celery starts one worker process per CPU of the machine it runs on, which can be more than the process’s memory holds. Two processes fit in H1 (0.3 GB of memory). To process more tasks at once, add instances in the process’s Scaling section, or choose a larger size and raise --concurrency. See Scaling.
Run tasks on a schedule
Run scheduled work as a cron job: add a command to the Flask CLI with@app.cli.command() in create_app(), then create a Cron job process with a Schedule in cron syntax, such as 0 3 * * * for every day at 03:00 UTC, and the command as its Custom start command, such as flask cleanup. See Cron jobs.
Verify
-
Queue a task, with your application’s domain:
The response is
{"status":"queued"}. -
Click the Logs tab and set Process to
Celery worker. The worker’s logs showTask app.tasks.send_order_confirmation[...] received, the lineSending the confirmation for order 42, andTask app.tasks.send_order_confirmation[...] succeeded.
getApplicationRuntimeLogsV3) with APP_ID from Deploy with the API:
sevalla apps logs runtime "$APP_ID" --search "order 42", and the MCP server with search_runtime_logs.
If the worker’s logs repeat consumer: Cannot connect to redis://localhost:6379/0, the application has no REDIS_URL: check that the internal connection added it on the Environment variables tab, then deploy again.
Deploy with the API
These calls create the Redis database, connect it, create the worker and deploy the code, as the dashboard steps on this page do.APP_ID, CLUSTER_ID, H1_ID and DB1_ID come from Deploy with the API in the deploy guide, which also turned on auto-deploy, and SEVALLA_API_KEY holds the same API key. Commit the code from this page first, without pushing it, and run the commands in the project folder: the push comes last, so one deployment adds the code, the variable and the worker together.
1
Create the Redis database
Create database (CLI:
createDatabaseV3), with a password you choose, because the API never returns it. The API requires db_name for every engine; a Redis database reports it as 0:sevalla databases create --name storefront-redis --type redis --db-version 8.6 --cluster "$CLUSTER_ID" --resource-type "$DB1_ID" --db-name storefront --db-password "$REDIS_PASSWORD". MCP: create_database with type redis, connect_to_application_id set to the application and env_var_name set to REDIS_URL does this step and the next three: it generates the password, connects the database and adds REDIS_URL as redis://:<password>@<host>:<port>, which uses database 0 too.2
Wait for the database
Get database (CLI:
getDatabaseV3) until its status is ready, then keep its internal hostname and port:sevalla databases get "$REDIS_ID" --json. MCP: get_database.3
Connect the database
Create internal connection (CLI:
createApplicationInternalConnectionV3):sevalla databases connections internal-create "$REDIS_ID" --target-id "$APP_ID" --target-type app. MCP: sevalla_api_create with createApplicationInternalConnectionV3 and the same body.4
Add the Redis URL
The API doesn’t add the connection’s variables. Create environment variable (It prints
createEnvironmentVariableV3) adds REDIS_URL in the dashboard’s format, available during runtime only:{"key":"REDIS_URL","is_runtime":true,"is_buildtime":false}. If the application already has a REDIS_URL, from another of these guides, the call fails with 400 and Environment variable with key "REDIS_URL" already exists: use that Redis database instead of a new one, or replace the value with Update environment variable (updateEnvironmentVariableV3). CLI: sevalla apps env-vars create "$APP_ID" --key REDIS_URL --value "redis://:$REDIS_PASSWORD@$REDIS_HOST:$REDIS_PORT/0", which makes it available during build and runtime. MCP: set_environment_variables with runtime true and buildtime false.5
Create the worker
Create process (CLI:
createProcessV3), with the size and the instance count:sevalla apps processes create "$APP_ID" --name "Celery worker" --type worker --command "exec celery -A make_celery worker --loglevel INFO --concurrency 2" --resource-type "$H1_ID". MCP: sevalla_api_create with createProcessV3 and the same body.6
Push and find the deployment
Push the commit. Auto-deploy starts a deployment of it, and List deployments (With auto-deploy off, start it with Trigger deployment (
listDeploymentsV3), newest first, returns it once it exists:triggerDeploymentV3) instead. CLI: sevalla apps deployments list --app-id "$APP_ID". MCP: list_deployments.7
Wait for the deployment
Get deployment (It prints
getDeploymentV3) until status is success or failed:success when the deployment finishes, or failed; after 30 minutes without either, it prints the status it last read. CLI: sevalla apps deployments get "$DEPLOYMENT_ID" --app-id "$APP_ID". MCP: get_deployment, then get_deployment_logs if it failed.listApplicationDomainsV3) as in the deploy guide.