uv.lock and starts FastAPI with Uvicorn.
This guide builds a support agent for a store. The Storefront assistant looks up orders with a tool and hands returns off to the Returns agent, which starts them with a tool of its own.
At a glance
Environment variables
The dashboard makes the connection’s variables available during the build too; the build doesn’t need them.
Before you begin
- A Sevalla company with a payment method, and a GitHub, GitLab or Bitbucket account for the repository. See Git providers.
- An OpenAI API key for a project with credits. Set a budget on the project, so an agent stuck in a loop can’t run up the bill.
- Python 3.14 and uv 0.13 or later on your computer.
- Docker, to run PostgreSQL on your computer while you develop.
Create the project
Create the project with uv and add the SDK and FastAPI:uv init writes pyproject.toml, a .python-version with 3.14, a .gitignore that keeps out .venv, and a Git repository. uv add installs the packages into .venv and pins every version in uv.lock:
Define the agents
app/assistant.py
@function_toolturns a function into a tool. The SDK builds the tool’s schema from the type hints and the docstring, which the model reads to decide when to call it.handoffs=[returns_agent]gives the assistant a tool namedtransfer_to_returns_agent. When the model calls it, the returns agent takes over the conversation.MODELsets the model of both agents.gpt-6-lunais fast and costs $0.10 per 1M input tokens and $0.50 per 1M output tokens: a question that calls one tool uses about 300 input and 30 output tokens, and a return with a handoff about 440 and 100. ChangeMODELto use another model, such asgpt-6.1-solfor harder tasks.
Keep sessions in PostgreSQL
A session is the conversation the SDK remembers between runs.SQLAlchemySession keeps it in PostgreSQL, so every instance of the application sees the same conversations:
app/db.py
DB_URLis the variable Sevalla adds when you connect the database. It starts withpostgres://, which SQLAlchemy doesn’t accept, so the code puts the asyncpg driver’s scheme in its place.- A run with
session=session_for(...)loads the session’s earlier messages before it calls the model and saves the new ones when it ends. agent_runsis the queue of background runs.python -m app.dbcreates the tables, and does nothing to tables that exist. On Sevalla, a job runs it before each deployment, so 2 instances never race to create them.
Serve the agent
app/main.py
Authorization: Bearer followed by the value of the API_TOKEN environment variable. Without the header, FastAPI answers 401 with {"detail":"Not authenticated"}; with another token, 401 with {"detail":"Invalid token"}. The agent spends money on every request, so never leave it open.
Runner.run_streamed starts the run and stream_events() yields what happens as it happens. The route turns 4 kinds of events into Server-Sent Events, each with its data encoded as JSON:
EventSourceResponse sets Content-Type: text/event-stream and Cache-Control: no-cache, and while the agent sends nothing, it sends a : ping comment every 15 seconds to keep the connection open.
Run long tasks in a background worker
The worker takes queued runs fromagent_runs, oldest first, runs each one to the end and saves its output:
app/worker.py
with_for_update(skip_locked=True)locks the run’s row, and other workers skip locked rows, so each run happens once however many workers you start. While a run is in progress, its row readsqueued; it changes todoneorfailedwhen the run ends.- If the model call fails, the run’s status is
failedand itsoutputholds the error, for exampleError code: 401 - Incorrect API key provided. - On
SIGTERM, the worker finishes the run in progress, takes no new one, and exits withWorker stopped. See Shut down without losing work.
Run the agent on your computer
Start PostgreSQL in Docker, set the variables the code reads, and create the tables:OPENAI_API_KEY to your key. fastapi dev finds the application in app/main.py and serves it on http://127.0.0.1:8000. In a second terminal, ask about an order:
-N turns off curl’s buffering, so the events print as they arrive:
uv run python -m app.worker in a third terminal with the same variables. Press Ctrl+C to stop each one.
Prepare the project for Sevalla
The project already has what Ingot needs:
Uvicorn listens on all interfaces, on the port in the
PORT environment variable that Sevalla sets (8080 by default), and runs one worker process. The background worker and the job run their own commands in the same image, which you set when you create them. See Run workers and jobs.
Commit everything and push it to your Git provider. uv init already created the repository:
Deploy to Sevalla
These steps build with Ingot. To build from your own Dockerfile instead, see Deploy with a Dockerfile.1
Create the database
In the sidebar, click Databases, then click Create database. Under Database, choose PostgreSQL and the newest version. Enter
support-db as the Display name, choose a Data center and a Size, then click Create database. See Create a database for every field.2
Create the application
In the sidebar, click Applications, then click Create > Application. Under Source, click Private repository, then choose the Git provider, the Repository and the Branch. Under Location, choose the same Data center as the database. Keep the Size at H1 or choose a larger one, then click Create application. The application opens on its Overview tab with the status Not deployed yet: creating an application doesn’t deploy it.
3
Connect the database
Click the Networking tab. Under Connected services, click Add internal connection. Choose
support-db as the Service, turn on Add environment variables to the application, and click Add internal connection. Sevalla adds DB_URL and the other connection variables to the application. See Connect an application.4
Add the OpenAI key and the API token
Click the Environment variables tab, then click Add environment variables. Add
OPENAI_API_KEY with your OpenAI API key, click Add another, and add API_TOKEN with a long random value, for example the output of openssl rand -hex 32. Under Availability, keep Available during runtime selected and clear Available during buildtime, so the build never sees the secrets. Click Add environment variables.5
Create the migration job
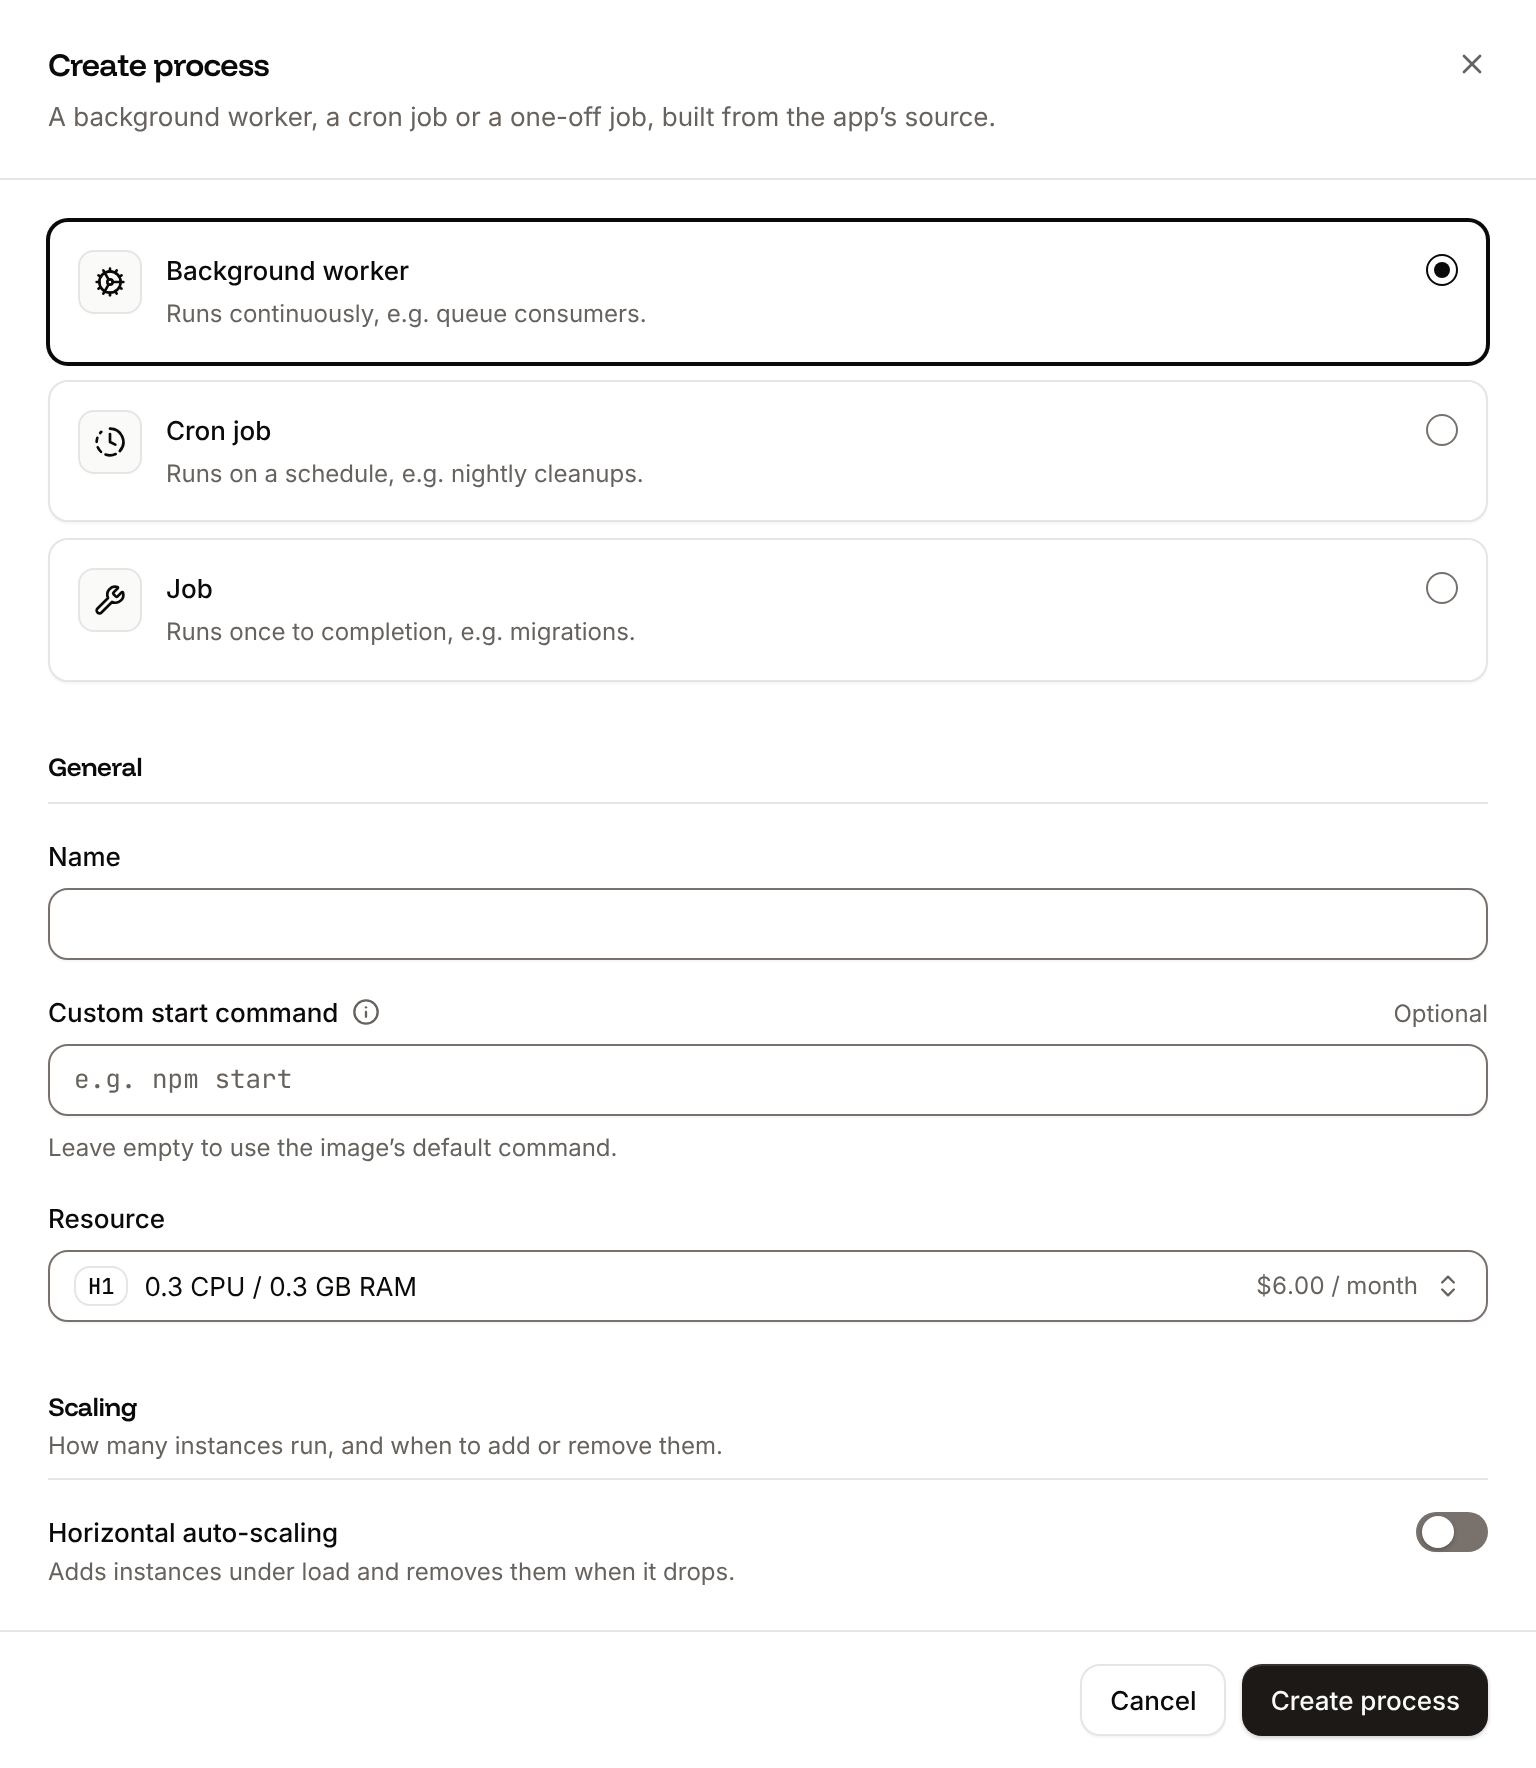
Click the Processes tab, then click Create process. Choose Job, enter
Migrate as the Name and python -m app.db as the Custom start command. Keep the Start policy at Before deployment and the Resource at H1, then click Create process.6
Create the background worker
Click Create process again. Choose Background worker, enter
Worker as the Name and exec python -m app.worker as the Custom start command. Keep the Resource at H1 and click Create process.7
Deploy
Click the Overview tab, then click Deploy now under Recent deployments. Check the Branch and click Deploy.
8
Turn on auto-deploy
To deploy every push to the branch automatically, click the Settings tab, then click Update auto-deploy in the Auto-deploy section. Turn on Auto-deploy and click Update auto-deploy. See Deployments.
exec, so Python replaces the shell that Sevalla runs the command in and receives SIGTERM itself. The web process, the worker and the job all run in H1 (0.3 vCPU, 0.3 GB of memory), the smallest size: in testing, each instance used 240 to 290 MB of memory and never restarted. For real traffic, choose S1 (1 GB) for headroom. See Instance sizes.
Verify the deployment
-
On the Deployments tab, click the deployment. Its build log shows Ingot’s build plan:
After the build, the log showsBuild log
Migrate has been successful,Web has been deployed successfullyandWorker has been deployed successfully. -
Wait for the deployment’s status to change to Deployed. The application’s status next to its name changes to Running. With the API, Get deployment (
getDeploymentV3) returns the status, and Get application deployment logs (getApplicationDeploymentLogsV3) searches the build log, with the IDs from Deploy with the API: -
Copy the domain under the application’s name, for example
support-agent-x7k2m.sevalla.app. A request without the token gets no further than FastAPI: -
Ask the agent about an order, with your
API_TOKEN. Thegrepcommands keep the names of the agents and tools from the stream:Without thegrepcommands, the whole stream prints: theagentevent at once,tool2 to 3 seconds later, then the answer’sdeltaevents anddonewith"Order 1001 has shipped.". -
Ask for a return in the same session:
The second
agentevent is the handoff, and the answer gives the return numberR-1002. Ask about the first order in the same session; the answer names order 1001, which the agent read from PostgreSQL: -
Queue a run for the worker, wait, and read its status:
The run’s
outputholds the answer. The worker’s runtime logs showRun <id> startedandRun <id> done. With the API, Get application runtime logs (getApplicationRuntimeLogsV3) finds the line; logs take a few seconds to arrive, so run it again if it prints0:
How streaming works on Sevalla
Cloudflare and Sevalla’s proxy pass each event to the client as the application writes it, with no buffering and no configuration: in testing, the 130delta events of a 120-word answer arrived spread over 2 seconds, as the model wrote them.
- Long pauses. Cloudflare ends a request that sends no bytes for too long with error
524(see 504 Gateway Timeout and Cloudflare error 524). The: pingcomment that FastAPI sends every 15 seconds keeps a stream open while the model thinks, and a stream that keeps sending stays open: a 5-minute test stream arrived complete. - Disconnects. When the client closes the connection, FastAPI stops the stream and the run with it. The session keeps the question but no answer. Queue work that must finish with
POST /runs. - Deployments. A deployment stops the instance that serves a stream, so a stream can end without its
doneevent. A client that doesn’t getdoneshould send the question again: the session keeps every earlier turn. See Shut down without losing work. - Caching. Sevalla never caches a request with an
Authorizationheader, even with edge caching on, so every request reaches the agent.
POST /chat when a person waits for the answer, and POST /runs when no one does: a webhook, a scheduled task, or a run longer than a client stays connected.
Shut down without losing work
When a deployment, a restart or a scale-down stops an instance, Sevalla waits 5 seconds, sendsSIGTERM, and stops the instance 30 seconds after the shutdown began. See How processes run.
- Web process. Uvicorn stops accepting connections and waits for the streams in progress. New requests already go to the new instances. In testing, streams in progress kept running for 25 seconds after
SIGTERM, then ended when Sevalla stopped the instance. The answers in this guide take 2 to 5 seconds. - Background worker. The worker finishes the run in progress, takes no new one, and logs
Worker stopped. In testing, the old worker finished its run during a deployment while the new worker took the next runs from the queue. If a run lasts longer than Sevalla waits, Sevalla stops the worker, PostgreSQL rolls the transaction back, and the run goes back toqueuedfor another worker to run again from the start. Tools that change data run again too, so make them safe to repeat:start_returnreturns the same return number for the same order.
Run more instances
Sevalla doesn’t keep a client’s requests on one instance, and the agent keeps nothing in memory between requests: sessions and runs live in PostgreSQL. So you can run 2 or more instances of the web process and of the worker. In testing, requests in the same session reached both of 2 web instances, and both remembered the customer’s name; 2 workers ran 4 queued runs between them, each run once. To add instances, update the process’s Instance count. See Set the number of instances.Tracing
The SDK traces every run (each model call, tool call and handoff, with their inputs and outputs) and sends the traces to OpenAI with yourOPENAI_API_KEY, in batches from a background thread. View them on the Traces dashboard. The SDK sends what’s left when the process exits, so a graceful shutdown keeps the last traces. Tracing isn’t available to organizations that use OpenAI’s APIs under a Zero Data Retention policy.
To change it, add an environment variable on the Environment variables tab and deploy:
Keep the agent safe
- Secrets stay out of the image.
OPENAI_API_KEYandAPI_TOKENare runtime-only variables, so builds and build logs never see them. - Every route needs the token. Bots scan new domains: in testing, requests for
/.envand/server-statusreached the agent within a minute of its first deployment. A request without the token never reaches the model. - Tools get the least access they need. The agent decides which tool to call from text that customers write, and text it reads (order notes, emails, web pages) can carry instructions meant to take it over. Give each tool only the data and actions it needs, and let your code, not the model, take actions you can’t undo, such as refunds. For an approval step that waits for a person, see Deploy a LangGraph agent.
- Spending has a limit. Set a budget on the OpenAI project, and watch the application’s requests on its Analytics tab.
Deploy with a Dockerfile
Ingot needs no Dockerfile. Write your own when you want full control of the image: the base image, the system packages and every layer. Add aDockerfile and a .dockerignore to the root of the repository:
Dockerfile
.dockerignore
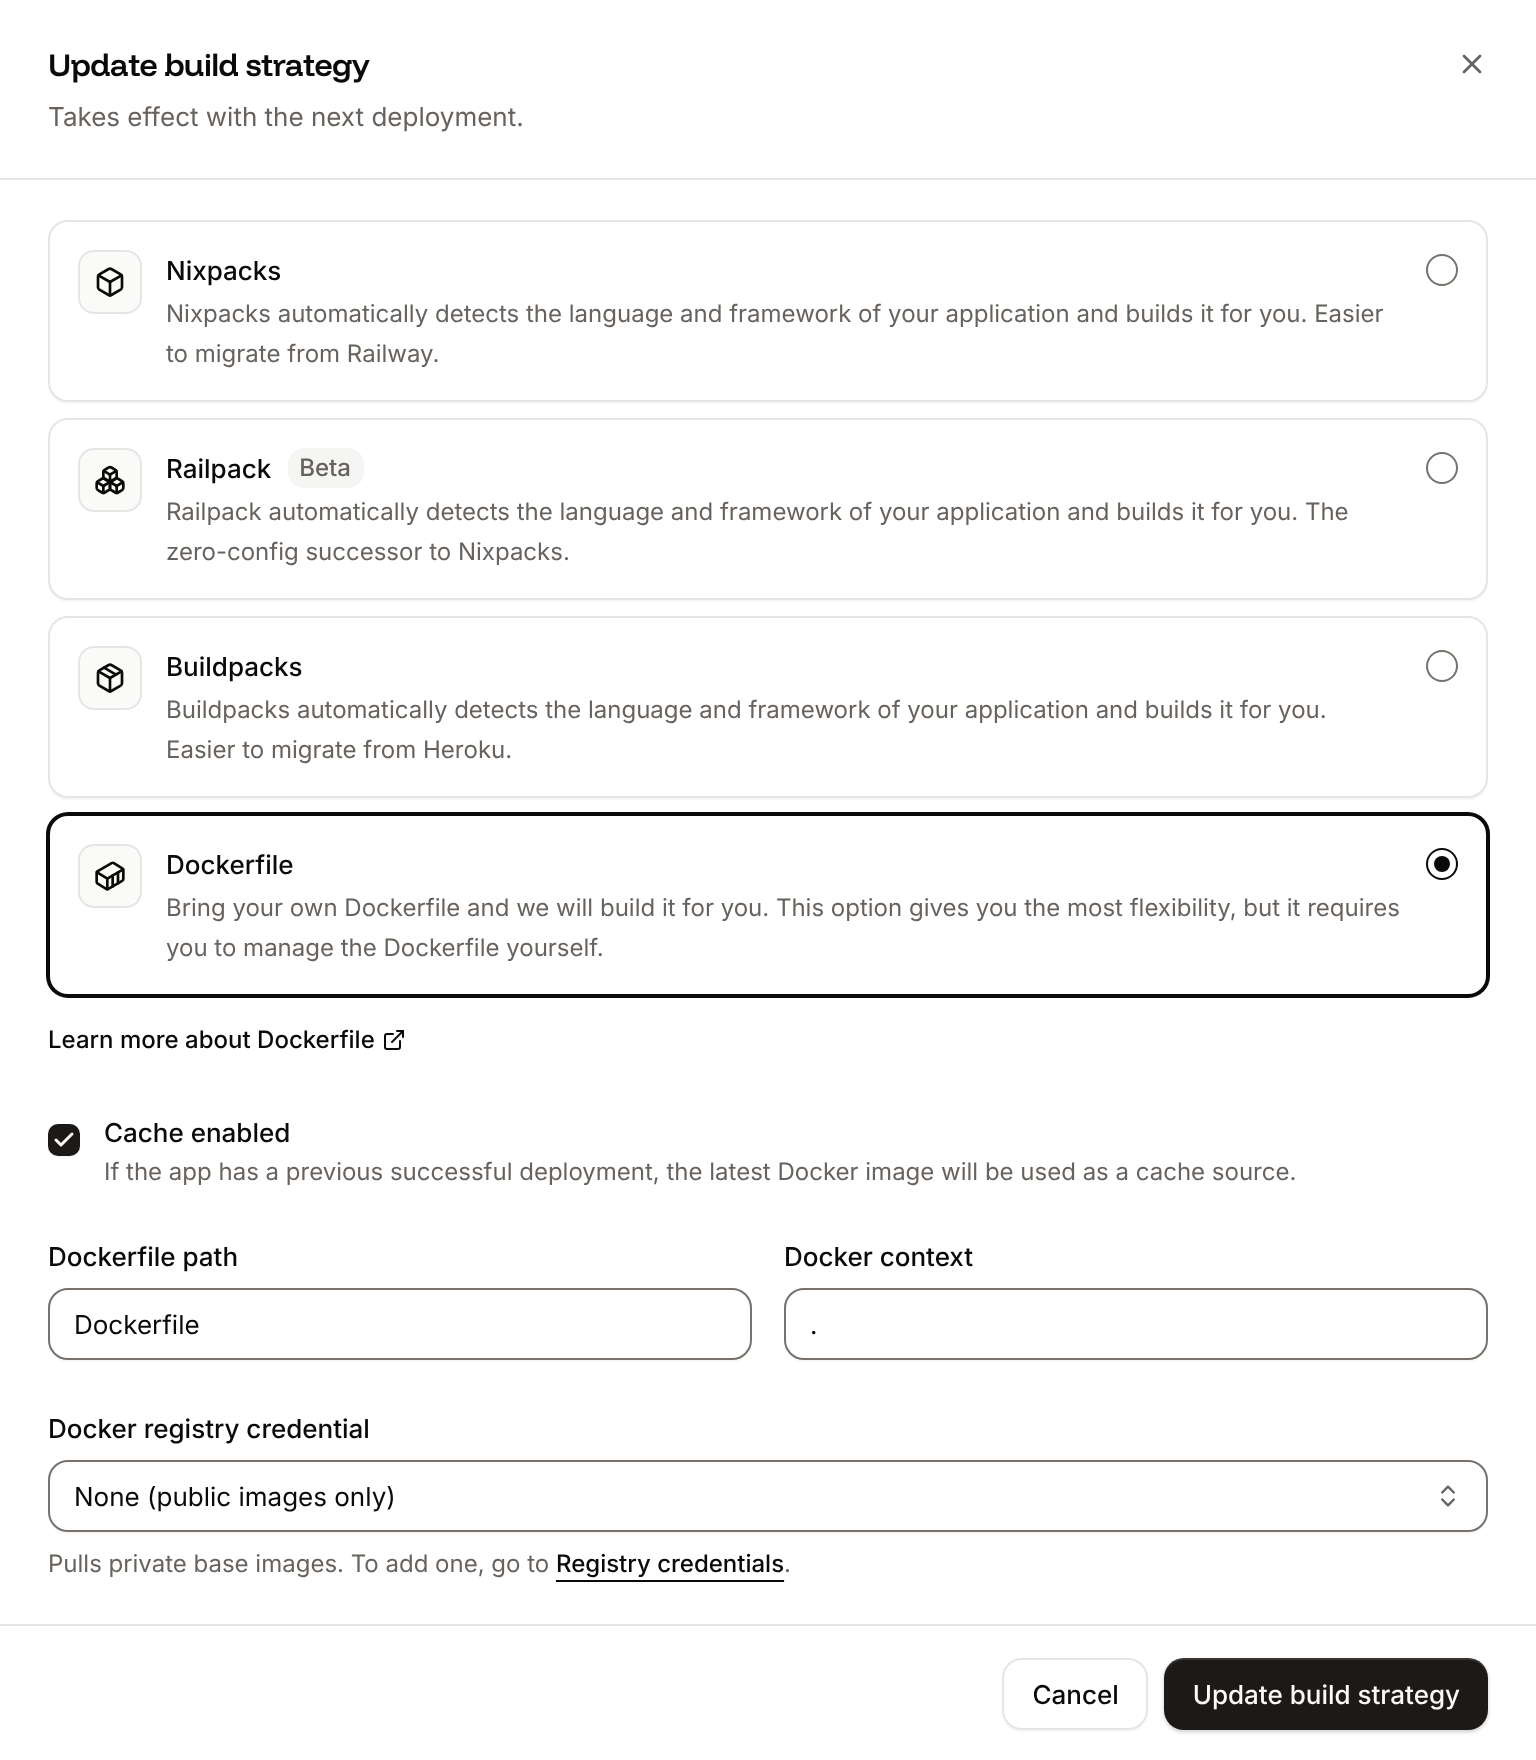
Dockerfile, so you can keep it in a repository that builds with Ingot, but it adds the .dockerignore patterns to its own: its build plan shows an Ignored row with 6 patterns from .dockerignore. Then switch the application to the Dockerfile build strategy:
1
Choose the Dockerfile build strategy
On the application’s Settings tab, in the Build strategy section, click Update build strategy. Click Dockerfile, keep the Dockerfile path
Dockerfile and the Docker context ., then click Update build strategy.2
Deploy
Click the Overview tab, then click Deploy now under Recent deployments. Check the Branch and click Deploy.
📦 Building and pushing docker image using Dockerfile... where Ingot’s build plan was, then Migrate has been successful: the job runs python -m app.db in the new image. With the API, for the new deployment’s ID:
curl requests, the session dana still remembers order 1001, and queued runs reach done. The deployment’s Dockerfile tab shows your Dockerfile. See Dockerfile.
Deploy changes
With Auto-deploy on, every push to the branch starts a deployment; otherwise, click Deploy now for each change. Each deployment builds the image, runs theMigrate job, then replaces the instances of the web process and the worker. After you add a package with uv add, commit pyproject.toml and uv.lock together. To store more in PostgreSQL, add tables to app/db.py: python -m app.db creates new tables but doesn’t change existing ones, so use a migration tool such as Alembic for changes to them. See Deployments.
Add a custom domain
To serve the agent from your own domain, such asagent.example.com, add the domain on the application’s Domains tab and create the DNS records that Sevalla shows. Custom domains need a web process larger than H1, so scale the web process first. See Custom domains.
Troubleshoot
For more causes, see Troubleshoot builds and deployments.
Deploy with the API
This sequence makes the same deployment as Deploy to Sevalla with the Sevalla API, for a script or an AI agent: each step is one call, and later steps use the IDs that earlier ones save in shell variables. It needscurl, jq and openssl, and:
- An API key with the Company developer role, or the
APP:CREATE,APP:READ,APP:UPDATE,DATABASE:CREATEandDATABASE:READpermissions. - The repository pushed to GitHub, with the Git account that can read it connected to Sevalla. If Sevalla can’t read the repository, the Create the application step fails with
400and a message that startsCannot access repositoryand says where to grant access. - Your OpenAI API key.
@sevalla/cli 2.1.0, which reads SEVALLA_API_TOKEN) and the MCP server can run each step too; each step names the command and the tool.
1
Pick a location
List clusters (CLI:
listClustersV3) returns every location with its display_name and location. This picks Frankfurt, Germany (eu-frankfurt-1):sevalla resources clusters. MCP: get_platform_options.2
Look up the sizes
List process resource types (CLI:
listProcessResourceTypesV3) and List database resource types (listDatabaseResourceTypesV3) return the sizes by name:sevalla resources process-types and sevalla resources db-types. MCP: get_platform_options.3
Create the database
Create database (CLI:
createDatabaseV3) needs the password you choose. The API never returns it, so keep it for DB_URL:sevalla databases create --name support-db --type postgresql --db-version 18 --cluster $CLUSTER_ID --resource-type $DB1_ID --db-name support --db-user support --db-password $DB_PASSWORD. MCP: create_database, which generates the password itself and never returns it; called after the application exists, with connect_to_application_id and env_var_name set to DB_URL, it also does the work of the internal connection step and adds DB_URL in the postgresql:// form, which app/db.py accepts.4
Wait for the database
Get database (CLI:
getDatabaseV3) reports status creating, then ready, with the internal hostname and port:sevalla databases get $DB_ID. MCP: get_database.5
Create the application
Create application (CLI:
createApplicationV3) creates the application with a web process and doesn’t deploy it:sevalla apps create --name support-agent --cluster $CLUSTER_ID --source privateGit --git-type github --repository $REPO --branch main. MCP: create_application with deploy set to false.6
Find the web process
List processes (CLI:
listProcessesV3):sevalla apps processes list --app-id $APP_ID. MCP: get_application.7
Set the web process to H1
The API creates the web process at S1, not the dashboard’s H1. Update process (It prints
updateProcessV3) sets the size:h1. CLI: sevalla apps processes update $WEB_ID --app-id $APP_ID --resource-type $H1_ID. MCP: scale_process with size_id and apply_now set to false.8
Connect the database
Create internal connection (CLI:
createApplicationInternalConnectionV3) opens the private network path. Unlike the dashboard, it adds no environment variables:sevalla apps internal-connections create $APP_ID --target-id $DB_ID --target-type database. MCP: sevalla_api_create with createApplicationInternalConnectionV3 and the same body.9
Add the environment variables
Create environment variable (CLI:
createEnvironmentVariableV3), once per variable, available during runtime only. DB_URL has the format the dashboard uses. Keep API_TOKEN for the checks.sevalla apps env-vars create $APP_ID --key API_TOKEN --value $API_TOKEN, which also makes the variable available during the build. MCP: set_environment_variables with runtime set to true and buildtime set to false.10
Create the migration job
Create process (CLI:
createProcessV3) needs resource_type_id and scaling_strategy for every type, and job_start_policy for a job. Without scaling_strategy, it answers 400 with Request doesn't match the schema; a job without job_start_policy gets jobStartPolicy must be provided if the process type is job.sevalla apps processes create $APP_ID --name Migrate --type job --resource-type $H1_ID --command "python -m app.db" --job-start-policy beforeDeployment. MCP: sevalla_api_create with createProcessV3 and the same body.11
Create the background worker
Create process (CLI:
createProcessV3) again:sevalla apps processes create $APP_ID --name Worker --type worker --resource-type $H1_ID --command "exec python -m app.worker". MCP: sevalla_api_create with createProcessV3 and the same body.12
Deploy
Trigger deployment (CLI:
triggerDeploymentV3) deploys the latest commit of the branch:sevalla apps deployments trigger $APP_ID. MCP: trigger_deployment.13
Wait for the deployment
Get deployment (It prints
getDeploymentV3) until status is success, or failed, cancelled or skipped:success. On failed, Get application deployment logs (getApplicationDeploymentLogsV3) returns the build log: curl -s "$API/applications/$APP_ID/deployments/$DEPLOYMENT_ID/logs?limit=5000" -H "$AUTH" | jq -r '.[].message'. CLI: sevalla apps deployments get $DEPLOYMENT_ID --app-id $APP_ID and sevalla apps deployments logs $DEPLOYMENT_ID --app-id $APP_ID. MCP: get_deployment and get_deployment_logs.14
Run the checks
List application domains (Then run the checks in Verify the deployment with
listApplicationDomainsV3) returns the domain:$HOST in place of support-agent-x7k2m.sevalla.app. CLI: sevalla apps domains list --app-id $APP_ID. MCP: get_application.