yarn build, which builds the API side and the web side, and the web process runs cedarjs-server, which serves the web side on the port that Sevalla sets in the PORT environment variable and passes /.api/functions requests to the GraphQL API in the same instance. The data lives in a Sevalla PostgreSQL database that Prisma reaches over an internal connection, and a job applies the Prisma migrations before each deployment.
This guide uses CedarJS 7, the maintained continuation of the RedwoodJS GraphQL framework. The RedwoodJS team renamed that framework Redwood GraphQL, released its last version, 8.9.0, on Oct 21, 2025, and now builds RedwoodSDK, a different framework that runs only on Cloudflare. Redwood GraphQL 8.9.0 requires Node.js 20, which reached its end of life in April 2026, and redwoodjs.com now redirects to RedwoodSDK; the RedwoodJS maintainers point Redwood GraphQL users to the documentation at cedarjs.com. CedarJS is a fork of Redwood GraphQL, maintained by one of its core contributors, and keeps Redwood’s sides, cells, services and SDL files, with the cedar CLI in place of rw. To move an existing RedwoodJS application, follow Migrating from RedwoodJS to CedarJS.
At a glance
Environment variables
The internal connection also adds
DB_HOST, DB_PORT, DB_DATABASE, DB_USERNAME and DB_PASSWORD, which the application doesn’t read.
Before you begin
- A Sevalla company with a payment method, and a GitHub, GitLab or Bitbucket account for the repository. See Git providers.
-
Node.js 24 on your computer, with Yarn enabled through Corepack:
corepack enable. CedarJS 7 needs Node.js 24 or later; Node.js 24 still ships Corepack. -
PostgreSQL on your computer, to create migrations against. With Docker:
Create the project
Create a CedarJS application with TypeScript and install its dependencies:api/, the GraphQL API with Prisma, and web/, the React application that Vite builds. package.json pins Node.js 24 in engines.node and Yarn 4.14.1 in packageManager, and its scripts are build (cedar build) and start (cedarjs-server).
Switch Prisma to PostgreSQL
The new project stores its data in SQLite. Replace the SQLite driver with Prisma’s PostgreSQL adapter, and makeprisma a dependency instead of a devDependency, so the image keeps the CLI that the migration job runs:
@7.8.0 keeps the adapter and the CLI on the Prisma version that CedarJS 7.1 installs for @prisma/client.
In api/db/schema.prisma, set the provider to postgresql and replace the UserExample model with a Comment model:
api/db/schema.prisma
api/src/lib/db.ts so that Prisma connects through the PostgreSQL adapter, with the address in DATABASE_URL:
api/src/lib/db.ts
.env, which .gitignore keeps out of the repository, then create the first migration:
.env
api/db/migrations/<timestamp>_init/migration.sql. Commit the api/db/migrations folder: the migration job applies what’s in it.
Add the API and the page
Generate the GraphQL schema and the service forComment, without the update and delete mutations:
@skipAuth, as the comments in Cedar’s tutorial do:
api/src/graphql/comments.sdl.ts
api/src/services/comments/comments.ts
web/src/components/CommentsCell/CommentsCell.tsx
web/src/pages/HomePage/HomePage.tsx
web/index.html holds no content until the JavaScript runs. Give it a title, so that the page has one before React renders. In web/index.html, add this line inside <head>:
web/index.html
Prepare the project for Sevalla
CedarJS already has what Sevalla needs:How Ingot builds and starts the application
- Ingot installs every dependency of both sides, then runs
yarn build, which runscedar build: it generates the Prisma client, builds the API side intoapi/distand the web side intoweb/dist.prisma generatedoesn’t connect to the database, butapi/prisma.config.cjsneeds aDATABASE_URL: during the build, CedarJS loads the placeholderDATABASE_URL=file:./db/dev.dbfrom.env.defaults, so keep that line. At runtime, theDATABASE_URLthat Sevalla sets takes precedence over.env.defaults. - After the build, Ingot removes the devDependencies with
yarn workspaces focus --all --production. The image keeps@cedarjs/api-server, which providescedarjs-server, andprisma, which you made a dependency. - The web process runs
cedarjs-server. It servesweb/distonPORT, which Sevalla sets (8080by default), on all network interfaces, starts the API server on port8911inside the instance, and passes requests for/.api/functionsto it. The page and the API share the application’s domain, so the browser needs no CORS setup. - Ingot doesn’t run migrations. A job runs
prisma migrate deployonce per deployment, before the new version starts. The image has no Yarn 4, so the job runs theprismacommand, notyarn cedar prisma.
cedarjs-server doesn’t handle SIGTERM: when Sevalla stops an instance, Node.js exits at once, and a request still running on that instance fails.
Run yarn cedar dev and open http://localhost:8910 to check the application locally; the API answers on http://localhost:8911. Then commit everything and push it to your Git provider. CedarJS’s .gitignore keeps .env, node_modules, dist and the generated Prisma client out of the repository:
Deploy to Sevalla
These steps build with Ingot. To build from your own Dockerfile instead, see Deploy with a Dockerfile.1
Create the database
In the sidebar, click Databases, then click Create database. Under Database, choose PostgreSQL and the newest version. Enter
storefront-db as the Display name, choose a Data center and a Size, then click Create database. See Create a database for every field.2
Create the application
In the sidebar, click Applications, then click Create > Application. Under Source, click Private repository, then choose the Git provider, the Repository and the Branch. Under Location, choose the same Data center as the database. Keep the Size at H1 or choose a larger one, then click Create application. The application opens on its Overview tab with the status Not deployed yet: creating an application doesn’t deploy it.
3
Connect the database
Click the Networking tab. Under Connected services, click Add internal connection. Choose
storefront-db as the Service and turn on Add environment variables to the application. In the list of variables, change the key DB_URL to DATABASE_URL, then click Add internal connection. See Connect an application.4
Create the migration job
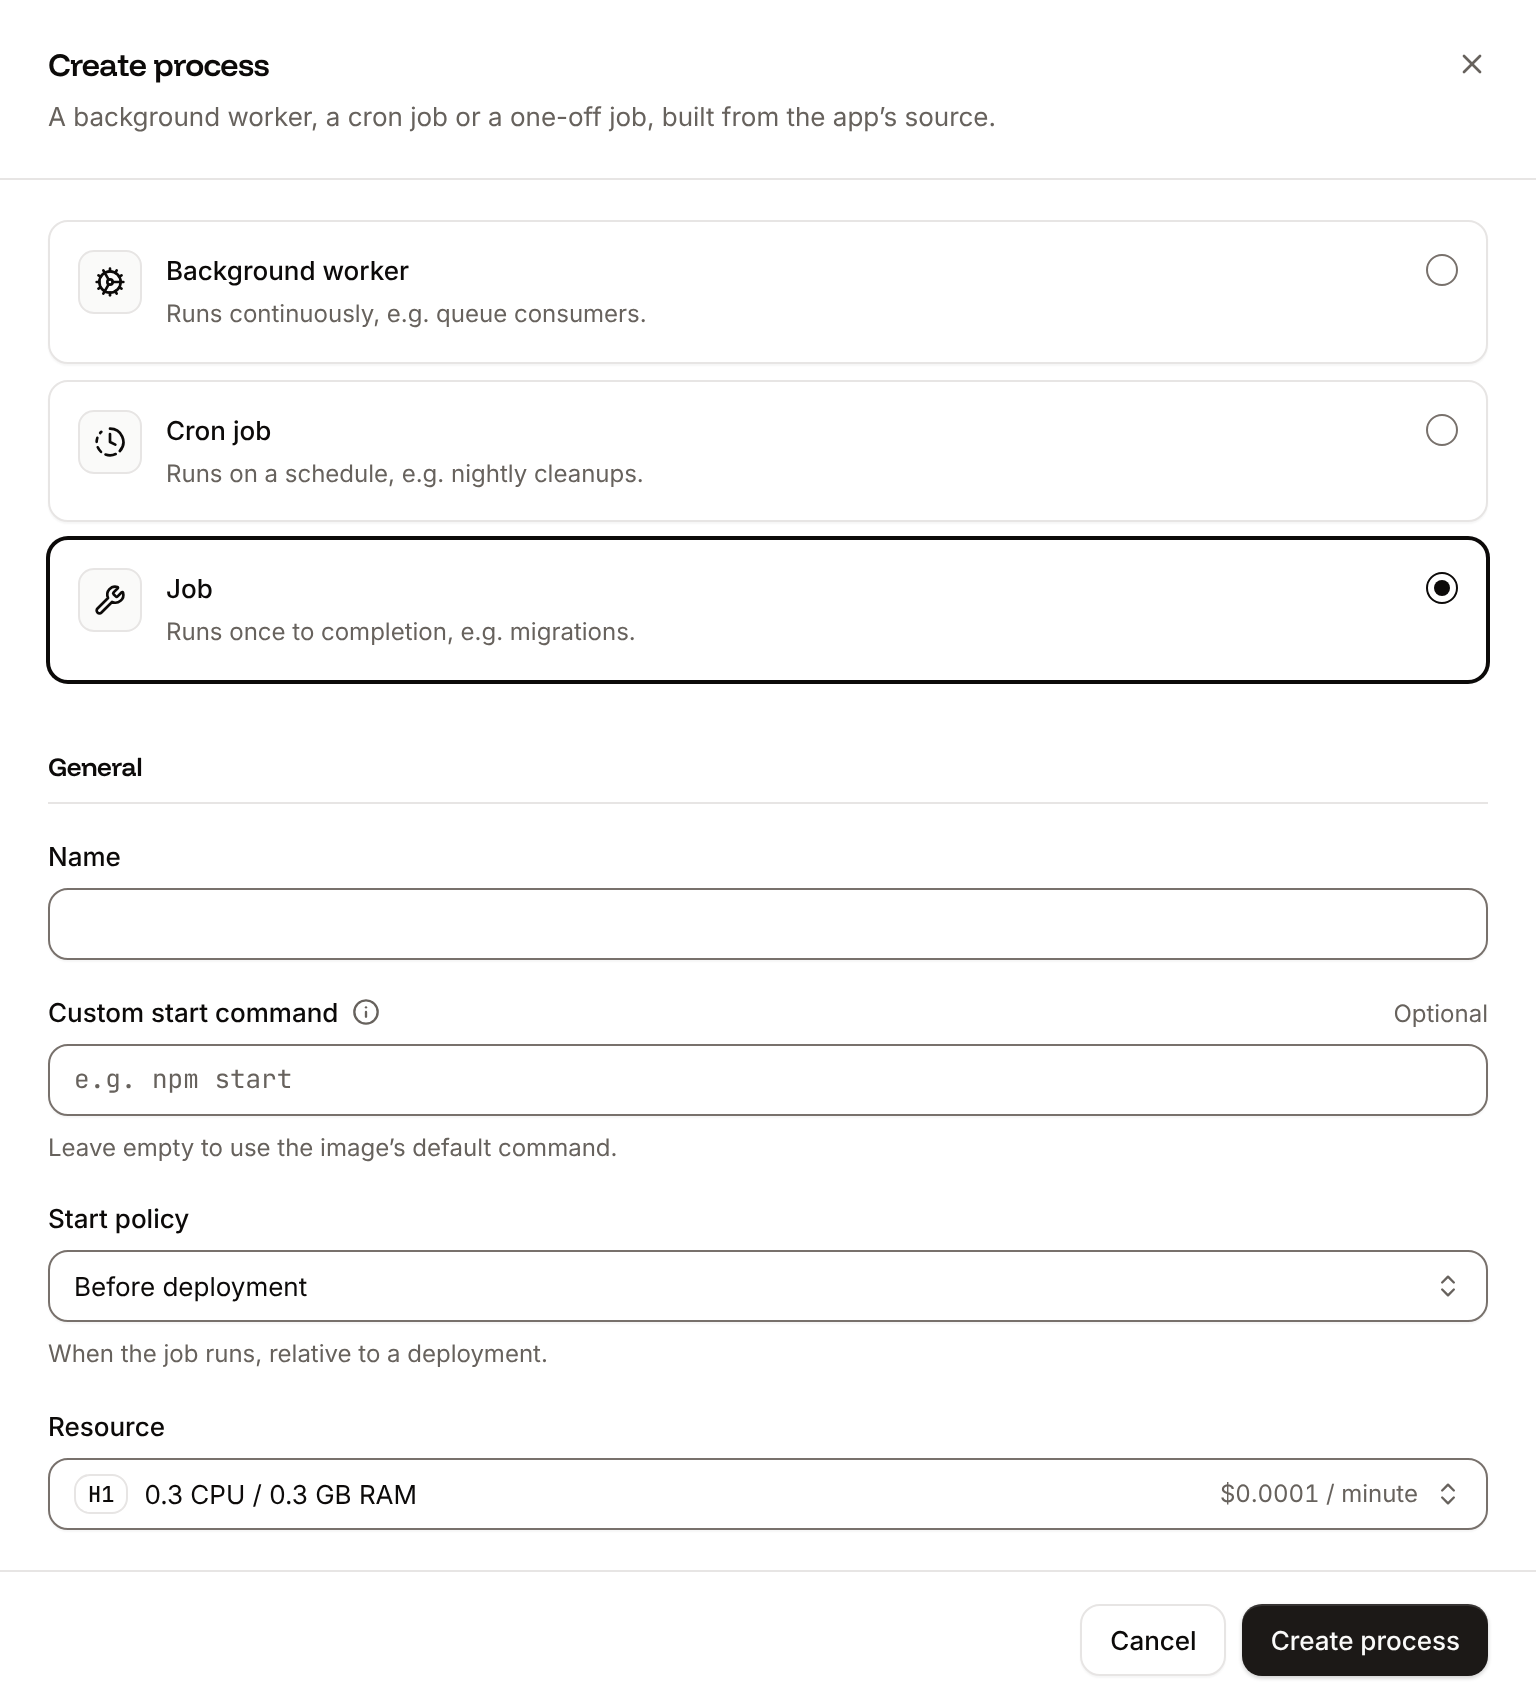
Click the Processes tab, then click Create process. Choose Job, enter
Migrate as the Name and prisma migrate deploy --config api/prisma.config.cjs as the Custom start command. Keep the Start policy at Before deployment and the Resource at H1, then click Create process.5
Add a readiness probe
On the Processes tab, click ⋯ on the web process, then click Update process. Under Health checks, turn on Readiness probe with the Path
/.api/functions/graphql/health, then click Update process. New instances get traffic only once both sides answer. See Health checks.6
Deploy
Click the Overview tab, then click Deploy now under Recent deployments. Check the Branch and click Deploy.
7
Turn on auto-deploy
To deploy every push to the branch automatically, click the Settings tab, then click Update auto-deploy in the Auto-deploy section. Turn on Auto-deploy and click Update auto-deploy. See Deployments.
Verify the deployment
-
On the Deployments tab, wait for the deployment’s status to change to Deployed. The application’s status next to its name changes to Running. Open the deployment to read its build log. Ingot’s build plan comes first:
Later, during the rollout, the log showsBuild log
Migrate has been successful. If the job fails, the deployment fails and nothing changes for visitors. -
Click the domain under the application’s name, for example
storefront-x7k2m.sevalla.app. The browser tab shows the titleHome | Storefront, and the page shows Storefront with the comments, orNo comments yet.before the first one. -
Check both sides from a terminal: the web side’s title, then a comment created and read through the GraphQL API:
Reload the page in the browser: it lists
Ada: Fast shipping.
getDeploymentV3) returns the deployment’s status, and Get application deployment logs (getApplicationDeploymentLogsV3) returns its build log. See Deploy with the API.
Deploy with a Dockerfile
Ingot needs no Dockerfile. Write your own when you want full control of the image: the base image, the system packages and every layer. Add aDockerfile and a .dockerignore to the root of the repository:
Dockerfile
.dockerignore
.dockerignore keeps your local .env out of the image, but not .env.defaults, which the build needs for its placeholder DATABASE_URL.
Commit and push both files. Ingot doesn’t use the Dockerfile, so you can keep it in a repository that builds with Ingot, but it adds the .dockerignore patterns to its own: its build plan then shows Ignored 11 patterns from .dockerignore, and the Ingot build still passes. Then switch the application to the Dockerfile build strategy:
1
Choose the Dockerfile build strategy
On the application’s Settings tab, in the Build strategy section, click Update build strategy. Click Dockerfile, keep the Dockerfile path
Dockerfile and the Docker context ., then click Update build strategy.2
Deploy
Click the Overview tab, then click Deploy now under Recent deployments. Check the Branch and click Deploy.
📦 Building and pushing docker image using Dockerfile... instead of Ingot’s build plan, then Migrate has been successful, and its Dockerfile tab shows your file. The Migrate job and DATABASE_URL stay as they are. When the deployment’s status is Deployed, the checks in Verify the deployment print the same lines, with the comments created so far. See Dockerfile.
Deploy changes
With Auto-deploy on, every push to the branch starts a deployment; otherwise, click Deploy now for each change. Each deployment builds the image, runs theMigrate job, then replaces the web process’s instances. To change the schema, edit api/db/schema.prisma, run yarn cedar prisma migrate dev --name <change> on your computer, and commit the new folder in api/db/migrations with the code that uses it. See Deployments.
Use environment variables
The API side reads every environment variable fromprocess.env. The web side sees only the variables that cedar.toml lists in includeEnvironmentVariables, or whose names start with REDWOOD_ENV_. Vite writes their values into the JavaScript during the build, so those variables must be available during the build, and anyone can read them in the browser. Add variables on the application’s Environment variables tab; they apply at the next deployment. See Environment variables.
Add a custom domain
To serve the application from your own domain, such asshop.example.com, add the domain on the application’s Domains tab and create the DNS records that Sevalla shows. Custom domains need a web process larger than H1, so scale the web process first. The web side calls the API on the same domain, so nothing else changes. See Custom domains.
Troubleshoot
For more causes, see Troubleshoot Ingot builds and Troubleshoot builds and deployments.
Deploy with the API
The Sevalla API makes the same deployment as Deploy to Sevalla without the dashboard. Run the steps in order in one shell: each step is one API call, and saves the IDs that later steps need in shell variables. Each step also names the CLI command and the MCP server tool that do the same. A variable that holdsnull means the call failed: run the curl command without its jq part to read the error.
You need:
- An API key with the Company developer role, or the
APP:CREATE,APP:READ,APP:UPDATE,DATABASE:CREATE,DATABASE:READandDATABASE:UPDATEpermissions, in theSEVALLA_API_KEYenvironment variable. The CLI reads the key fromSEVALLA_API_TOKEN. - The repository on GitHub, GitLab or Bitbucket, and a Git account that can read it connected to your Sevalla user, which only the dashboard can do. See Git providers. Creating the application checks the access: if Sevalla can’t read the repository, the call returns
400withCannot access repository https://github.com/acme/storefront: Repository not found or you don't have access., followed by where to grant the access. openssl, to generate the database password, andcurlandjq.
1
Find the location
List clusters (CLI:
listClustersV3) returns every location with its id, its name in display_name and its region ID in location. Pick one by its region ID, here eu-frankfurt-1 for Frankfurt, Germany. Locations lists them all.sevalla resources clusters. MCP: get_platform_options.2
Find the database size
List database resource types (CLI:
listDatabaseResourceTypesV3) returns the ID of each database size. Pick DB1, the smallest, or a larger one:sevalla resources db-types. MCP: get_platform_options.3
Find the newest PostgreSQL version
List database versions (CLI:
listDatabaseVersionsV3) returns the versions the location offers, oldest first:sevalla resources db-versions --cluster "$CLUSTER_ID" --type postgresql. MCP: create_database picks the newest version when you leave out version.4
Create the database
Create database (CLI:
createDatabaseV3) creates storefront-db with the database storefront, the user storefront and a password you generate. The API doesn’t return the password later, and DATABASE_URL needs it, so keep it in DB_PASSWORD:sevalla databases create --name storefront-db --type postgresql --db-version "$PG_VERSION" --cluster "$CLUSTER_ID" --resource-type "$DB_SIZE_ID" --db-name storefront --db-user storefront --db-password "$DB_PASSWORD". MCP: create_database generates the password itself and never returns it. With connect_to_application_id and env_var_name set to DATABASE_URL, it also connects the database and adds DATABASE_URL as postgresql://..., which Prisma reads like postgres://; it replaces the Connect the database and Add DATABASE_URL steps, and needs the application first.5
Wait for the database
Get database (
getDatabaseV3) returns the database’s status, creating until it’s ready, and its internal hostname and port, which DATABASE_URL needs. Poll it every 10 seconds, for up to 10 minutes:internal_port is a string, such as "5432". CLI: sevalla databases get "$DB_ID". MCP: get_database.6
Create the application
Create application (CLI:
createApplicationV3) creates the application with the Ingot build strategy and a web process, and doesn’t deploy it.sevalla apps create --name storefront --cluster "$CLUSTER_ID" --source privateGit --git-type github --repository https://github.com/acme/storefront --branch main. MCP: create_application with deploy set to false.7
Find the web process
List processes (CLI:
listProcessesV3) returns the web process that Create application added:sevalla apps processes list --app-id "$APP_ID". MCP: get_application, in processes.8
Find the H1 size
The API creates the web process with the S1 size, where the dashboard picks H1. List process resource types (CLI:
listProcessResourceTypesV3) returns the ID of each size:sevalla resources process-types. MCP: get_platform_options.9
Set the web process size and readiness probe
Update process (CLI:
updateProcessV3) sets the size and adds the readiness probe from Deploy to Sevalla, so a new instance gets requests only once both sides answer. The probe’s other values are the dashboard’s defaults. Send timeoutSeconds: a probe set through the API without it waits 120 seconds for an answer, not the dashboard’s 1.sevalla apps processes update "$WEB_ID" --app-id "$APP_ID" --resource-type "$H1_ID" sets the size; the CLI has no option for probes. MCP: sevalla_api_update with updateProcessV3 and the same body.10
Connect the database
Create internal connection (CLI:
createApplicationInternalConnectionV3) lets the application reach storefront-db over the private network. Unlike the dashboard, it adds no environment variables: the next step adds DATABASE_URL.sevalla apps internal-connections create "$APP_ID" --target-id "$DB_ID" --target-type database. MCP: sevalla_api_create with createApplicationInternalConnectionV3 and the same body.11
Add DATABASE_URL
Create environment variable (CLI:
createEnvironmentVariableV3) adds DATABASE_URL in the format the dashboard uses for DB_URL. The server and the Migrate job read it when they start, and the build doesn’t need it, so it’s available during runtime only:sevalla apps env-vars create "$APP_ID" --key DATABASE_URL --value "postgres://...", which makes the variable available during the build too. MCP: set_environment_variables with runtime set to true and buildtime set to false.12
Create the migration job
Create process (CLI:
createProcessV3) adds the Migrate job, which applies the Prisma migrations before each deployment. The API needs the size in resource_type_id, the scaling_strategy, and the job_start_policy that the dashboard calls Before deployment:sevalla apps processes create "$APP_ID" --name Migrate --type job --resource-type "$H1_ID" --command "prisma migrate deploy --config api/prisma.config.cjs" --job-start-policy beforeDeployment. MCP: sevalla_api_create with createProcessV3 and the same body.13
Turn on auto-deploy
Update application (CLI:
updateApplicationV3) with auto_deploy deploys every push to the branch:sevalla apps update "$APP_ID" --data '{"auto_deploy":true}'. MCP: sevalla_api_update with updateApplicationV3, the application ID as path_params.id and the same body.14
Deploy
Trigger deployment (CLI:
triggerDeploymentV3) deploys the latest commit of the branch:sevalla apps deployments trigger "$APP_ID". MCP: trigger_deployment.15
Wait for the deployment
Get deployment (The loop asks every 15 seconds, for up to 30 minutes, and keeps asking through an empty or failed reply. CLI:
getDeploymentV3) returns the deployment’s status: waiting, inProgress, then success, failed, cancelled or skipped. Poll it until the deployment ends:sevalla apps deployments get "$DEPLOYMENT_ID" --app-id "$APP_ID". MCP: get_deployment.16
Read the build log
Get application deployment logs (With a Dockerfile, the log shows
getApplicationDeploymentLogsV3) returns the build log, one line per entry. With Ingot, the Start row of the build plan shows the start command, and the rollout reports the Migrate job. Without limit, the call returns the latest 1,000 lines; 5000 is the most it allows:📦 Building and pushing docker image using Dockerfile... in place of the build plan. When the job fails, the log ends with Migrate has failed, the deployment fails, and the runtime logs hold the job’s error. CLI: sevalla apps deployments logs "$DEPLOYMENT_ID" --app-id "$APP_ID". MCP: get_deployment_logs.17
Read the Migrate job output
Get application runtime logs (CLI:
getApplicationRuntimeLogsV3) returns what the processes print, the Migrate job included. prisma migrate deploy ends with All migrations have been successfully applied., or No pending migrations to apply. when the database is up to date:sevalla apps logs runtime "$APP_ID" --search "migrations". MCP: search_runtime_logs with search set to migrations.18
Check the application
List application domains (CLI:
listApplicationDomainsV3) returns the application’s domain. Request the web side’s title, then create and read a comment through the GraphQL API:sevalla apps domains list --app-id "$APP_ID". MCP: get_application, in domains.Build from the Dockerfile with the API
After you push theDockerfile and .dockerignore from Deploy with a Dockerfile, Update application (updateApplicationV3) switches the build strategy. Then repeat the Deploy, Wait for the deployment and Check the application steps:
sevalla apps update "$APP_ID" --data '{"build_type":"dockerfile","dockerfile_path":"Dockerfile","docker_context":"."}'. MCP: sevalla_api_update with updateApplicationV3 and the same body.