hanami assets compile, sets HANAMI_ENV to production, and starts Puma with the config.ru that hanami new writes, on the port in the PORT environment variable. A job runs the migrations before each deployment, and the data lives in a Sevalla PostgreSQL database that the application reaches over an internal connection.
At a glance
Environment variables
The internal connection also adds
DB_HOST, DB_PORT, DB_DATABASE, DB_USERNAME and DB_PASSWORD, which the application doesn’t read. Ingot sets HANAMI_ENV and RACK_ENV to production in the image.
Before you begin
- A Sevalla company with a payment method, and a GitHub, GitLab or Bitbucket account for the repository. See Git providers.
- Ruby 4.0, Node.js and PostgreSQL on your computer. Hanami compiles its assets with esbuild, which runs on Node.js.
Create the project
Install Hanami, then create an application namedstorefront that uses PostgreSQL:
hanami new installs Hanami 3.0 and Puma 8.0 with Bundler, installs the asset tools with npm, and runs git init. Generate a migration, a relation and a repository for products, an action and a view that list them, and an action that adds one:
config/db/migrate, with a timestamp in its name:
config/db/migrate/20261030073914_create_products.rb
app/repos/product_repo.rb
app/views/products/index.rb
app/templates/products/index.html.erb
app/actions/products/create.rb
config.formats.accept :json parses the JSON body into request.params and answers requests of another content type with 415. Then replace the routes that the generators added, so the products are the home page and /health answers the readiness probe:
config/routes.rb
/health is a Rack endpoint: it answers OK without loading an action, a view or the database.
Prepare the project for Sevalla
Pin the Ruby version
Ingot builds on Ruby 4.0, its default line, unless the project sets a version. Pin the line in theGemfile, under the source line, so the build doesn’t change when a new Ingot release moves its default:
Gemfile
bundle install to record the Ruby version in Gemfile.lock. See Pin the Ruby version.
Serve the assets
hanami assets compile writes the CSS, JavaScript and images, with a hash in each name, to public/assets, and the layout links them, for example /assets/app-GVDAEYEC.css. In production, Hanami serves those files only when HANAMI_SERVE_ASSETS is true: without it, every page loads, and every asset returns 404. Sevalla has no separate file server for an application, so set the variable when you deploy. Sevalla’s CDN can cache the files at Cloudflare’s edge.
Run the migrations without a dump
bundle exec hanami db migrate runs the migrations, then dumps the database’s structure to config/db/structure.sql with pg_dump. The image has no pg_dump, so on Sevalla the job fails after migrating, with No such file or directory - pg_dump (Errno::ENOENT). The --no-dump option skips the dump. Keep dumping on your computer, and commit config/db/structure.sql.
The job uses hanami db migrate, not hanami db prepare: prepare first checks that the database exists with psql, which the image doesn’t have either.
How Ingot builds and starts the project
The project needs no build or start configuration:
From these files, Ingot:
- Installs the gems with
BUNDLE_DEPLOYMENTset, so the build fails ifGemfile.lockdoesn’t match theGemfile, and leaves out thedevelopmentandtestgroups. - Adds Node.js 24 to the build, runs
npm ciandbundle exec hanami assets compile, then removesnode_modules. Node.js isn’t in the final image, and the build needs noDATABASE_URL. - Sets
HANAMI_ENV=production. - Starts the web process with
bundle exec puma --bind "tcp://0.0.0.0:$PORT": Puma listens on all network interfaces and on the port inPORT, which Sevalla sets to the web process’s port (8080by default). - Doesn’t touch the database. The
Migratejob runs the migrations once per deployment, before the new version starts.
HANAMI_WEB_CONCURRENCY to the number of Puma processes, for example 2. Hanami reads HANAMI_WEB_CONCURRENCY, not WEB_CONCURRENCY.
Run the application locally to check it, then open http://localhost:2300:
db prepare creates the local databases from DATABASE_URL in the .env file that hanami new wrote, runs the migration and writes config/db/structure.sql. Commit everything and push it to your Git provider:
hanami new already ran git init, and its .gitignore keeps node_modules, the compiled assets in public and .env*.local files out of the repository. The .env file holds the local DATABASE_URL, and production doesn’t load it: Hanami reads .env files with the dotenv gem, which is in the development and test groups.
Deploy to Sevalla
These steps build with Ingot. To build from your own Dockerfile instead, see Deploy with a Dockerfile.1
Create the database
In the sidebar, click Databases, then click Create database. Under Database, choose PostgreSQL and the newest version. Enter
orders-db as the Display name, choose a Data center and a Size, then click Create database. See Create a database for every field.2
Create the application
In the sidebar, click Applications, then click Create > Application. Under Source, click Private repository, then choose the Git provider, the Repository and the Branch. Under Location, choose the same Data center as the database. Keep the Size at H1 or choose a larger one, then click Create application. The application opens on its Overview tab with the status Not deployed yet: creating an application doesn’t deploy it.
3
Connect the database
Click the Networking tab. Under Connected services, click Add internal connection. Choose
orders-db as the Service and turn on Add environment variables to the application. In the list of variables, rename DB_URL to DATABASE_URL, then click Add internal connection. See Connect an application.4
Add the environment variable
Click the Environment variables tab, then click Add environment variables. Add
HANAMI_SERVE_ASSETS with the value true and click Add environment variables.5
Create the migration job
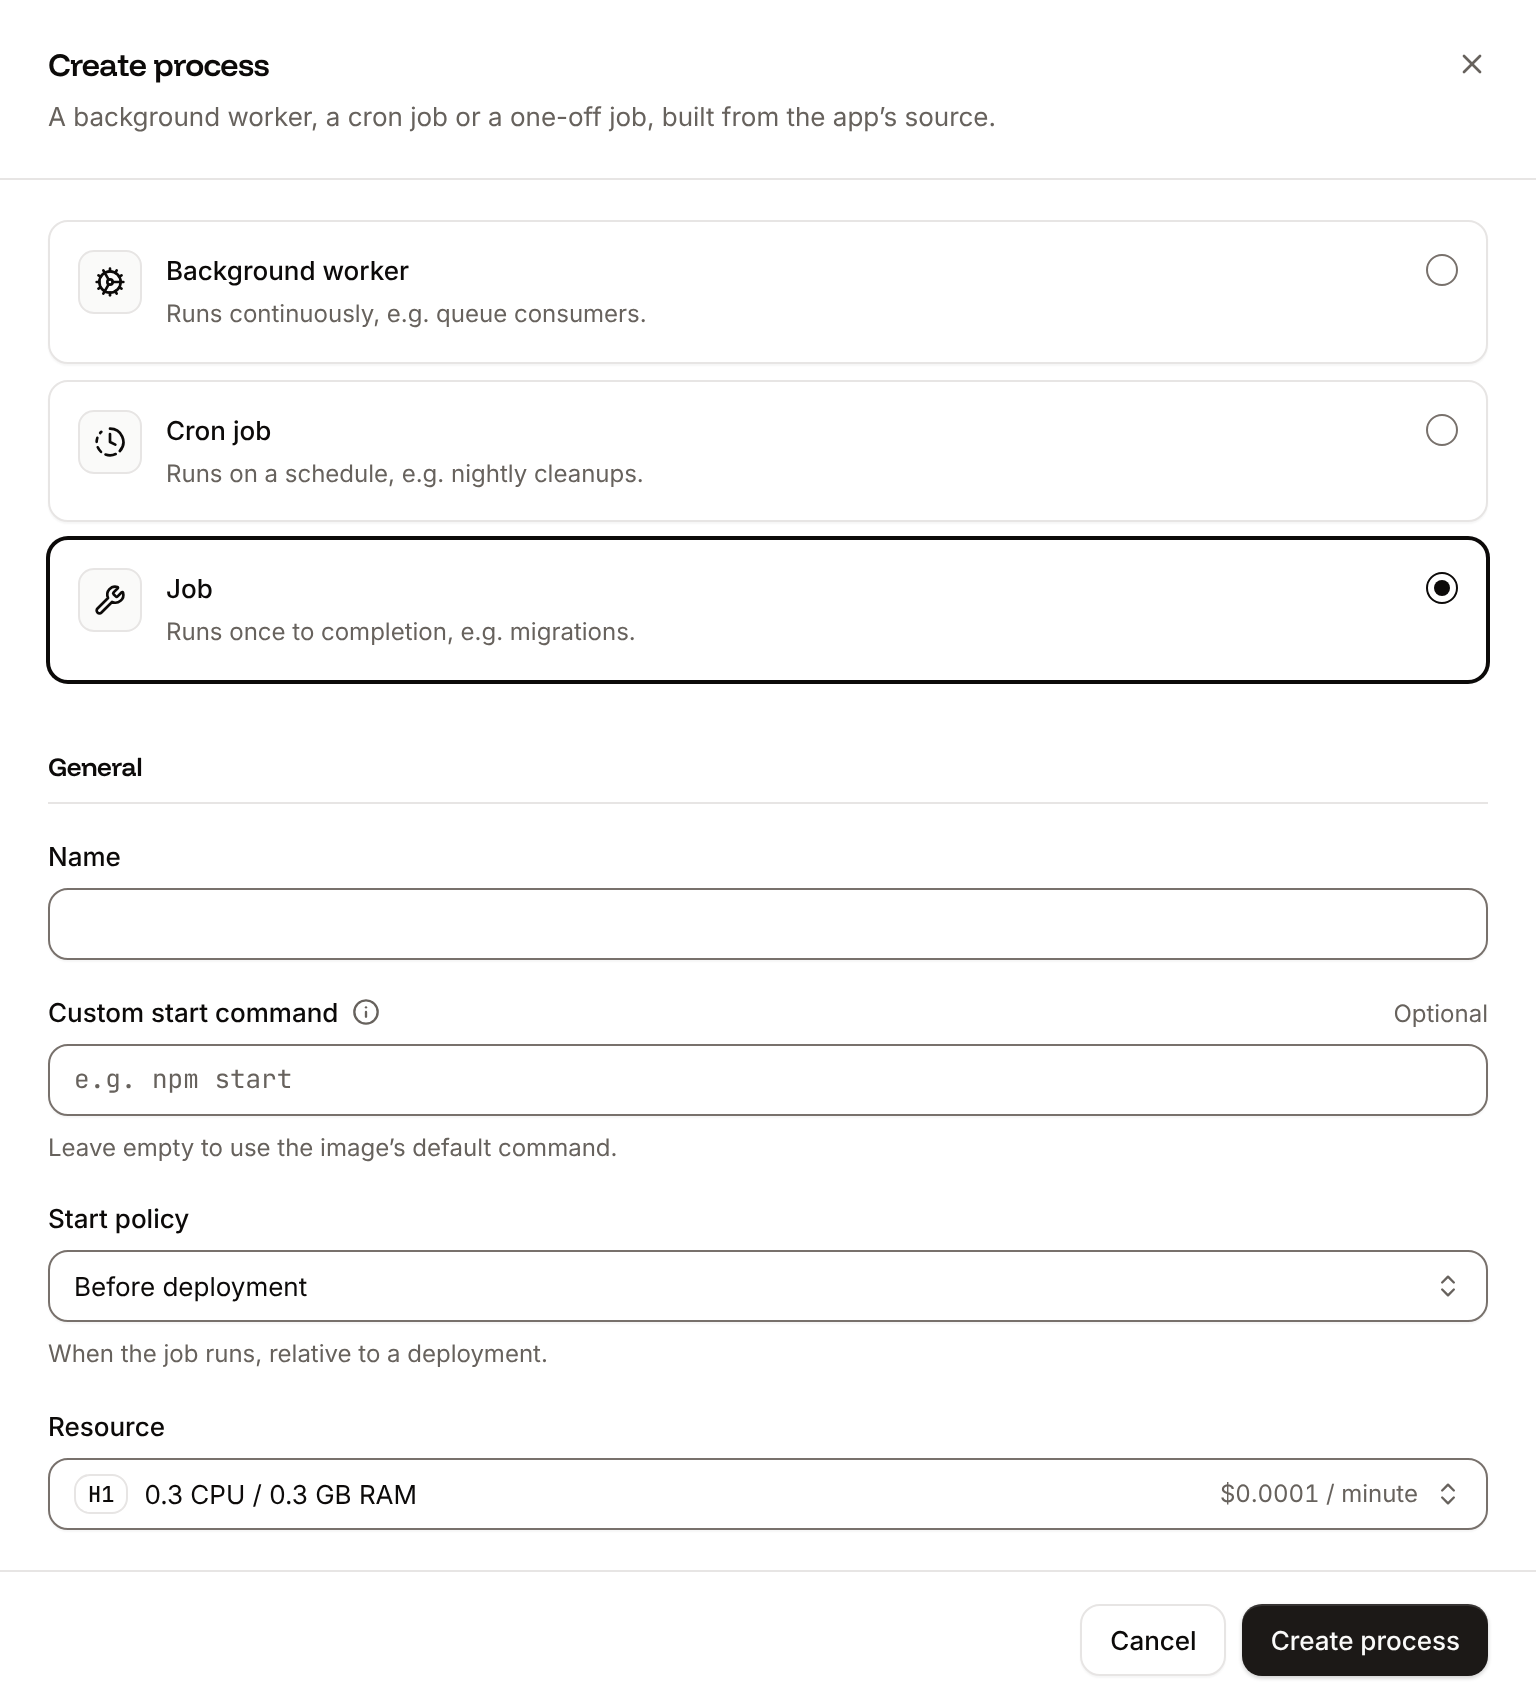
Click the Processes tab, then click Create process. Choose Job, enter
Migrate as the Name and bundle exec hanami db migrate --no-dump as the Custom start command. Keep the Start policy at Before deployment and the Resource at H1, then click Create process.6
Turn on the readiness probe
On the Processes tab, click ⋯ on the Web process, then click Update process. Under Health checks, turn on Readiness probe and set the Path to
/health, then click Update process. Each new instance gets traffic only once Hanami answers on /health.7
Deploy
Click the Overview tab, then click Deploy now under Recent deployments. Check the Branch and click Deploy.
8
Turn on auto-deploy
To deploy every push to the branch automatically, click the Settings tab, then click Update auto-deploy in the Auto-deploy section. Turn on Auto-deploy and click Update auto-deploy. See Deployments.
Verify the deployment
-
On the Deployments tab, wait for the deployment’s status to change to Deployed. The application’s status next to its name changes to Running. Open the deployment to read its build log. Ingot’s build plan comes first:
Later, the build log lists the compiled assets, such asBuild log
public/assets/app-GVDAEYEC.css, and, during the rollout,Migrate has been successful. - Click the domain under the application’s name. The Products page opens, with an empty list.
Environment: production and Listening on http://0.0.0.0:8080. Hanami’s mailer also logs No SMTP configuration found for storefront in production at start: the application sends no email, so you can ignore it, or set the SMTP_* variables that .env lists when you add mailers. To run commands on the running application, click the Web terminal tab. See Web terminal.
Check from a terminal
These checks need no dashboard. The API calls useAPI, H, APP_ID and DEPLOYMENT_ID as set in Deploy with the API.
-
The deployment’s status, from Get deployment (
getDeploymentV3): -
The rollout’s results in the build log, from Get application deployment logs (
getApplicationDeploymentLogsV3). The messages carry terminal color codes, whichgsubremoves, andselectdrops the lines of the image build, which start with#: -
The health route that the readiness probe requests, with your domain:
-
A product added through the JSON action, then the home page that lists it, which need the database:
-
The stylesheet the page links, which
HANAMI_SERVE_ASSETSserves:
422 with {"name":["must be filled"]}.
Deploy with a Dockerfile
Ingot needs no Dockerfile. Use one when you want full control of the image: the base image, the system packages and every layer. Add aDockerfile and a .dockerignore to the root of the repository:
Dockerfile
.dockerignore
Dockerfile, and it applies the .dockerignore patterns to its own build (its build plan shows Ignored 11 patterns from .dockerignore), so the repository still builds with Ingot. Then switch the application to the Dockerfile build strategy:
1
Choose the Dockerfile build strategy
On the application’s Settings tab, in the Build strategy section, click Update build strategy. Click Dockerfile, keep the Dockerfile path
Dockerfile and the Docker context ., then click Update build strategy.2
Deploy
Click the Overview tab, then click Deploy now under Recent deployments. Check the Branch and click Deploy.
📦 Building and pushing docker image using Dockerfile... instead of Ingot’s build plan, then Migrate has been successful. The checks in Check from a terminal return the same results, and the deployment’s Dockerfile tab shows the file the image was built from. See Dockerfile.
Deploy changes
With Auto-deploy on, every push to the branch starts a deployment; otherwise, click Deploy now for each change. Each deployment builds the image, runs theMigrate job, then replaces the web process’s instances. For a schema change, generate a migration with bundle exec hanami generate migration, run bundle exec hanami db migrate locally, and commit the migration with config/db/structure.sql. When you add a gem or an npm package, commit Gemfile.lock or package-lock.json with it. See Deployments.
Use environment variables
Read settings withENV.fetch("NAME"), or define them in config/settings.rb. Add them on the application’s Environment variables tab: they apply at the next deployment. hanami assets compile runs during the build without the runtime variables, and doesn’t need the database. See Environment variables.
Add a custom domain
To serve the application from your own domain, such asshop.example.com, add the domain on the application’s Domains tab and create the DNS records that Sevalla shows. Custom domains need a web process larger than H1, so scale the web process first. See Custom domains.
Troubleshoot
For more causes, see Troubleshoot Ingot builds and Troubleshoot builds and deployments.
Deploy with the API
The same deployment as Deploy to Sevalla, as calls to the Sevalla API that a script or an AI agent runs in order. Each step names the matching CLI command and Sevalla MCP server tool. The sequence needs:- An API key with the Company developer role, or the capabilities to create, read and update applications and databases, in
SEVALLA_API_KEY. - The repository pushed to GitHub, and a GitHub account with access to it connected to Sevalla. Connecting one is a dashboard step, and the API has no call that reports it: if no connected account can read the repository, the step that creates the application fails with
400and a message that starts withCannot access repositoryand says where to connect one. curl,jqandopenssl.
1
Choose the location
List clusters (CLI:
listClustersV3) returns every location your company can use, with its region ID in location. Pick one by region ID, here Frankfurt, Germany (eu-frankfurt-1); Locations lists the others. Display names differ between environments, so don’t select by them:sevalla resources clusters. MCP: get_platform_options.2
Look up the sizes and the PostgreSQL version
List database resource types (CLI:
listDatabaseResourceTypesV3), List process resource types (listProcessResourceTypesV3) and List database versions (listDatabaseVersionsV3) give the IDs of DB1 and H1 and the newest PostgreSQL version in the location:sevalla resources db-types, sevalla resources process-types and sevalla resources db-versions --cluster $CLUSTER_ID. MCP: get_platform_options for the sizes, and sevalla_api_read with listDatabaseVersionsV3 for the version.3
Create the database
Create database (The database starts as CLI:
createDatabaseV3). You choose the password, and the API never returns it, so keep it in a variable for the environment variables:creating. Poll Get database (getDatabaseV3) until it’s ready. On error, delete the database and create it again:sevalla databases create --name orders-db --type postgresql --db-version $PG_VERSION --cluster $CLUSTER_ID --resource-type $DB1_ID --db-name storefront --db-user storefront --db-password $DB_PASSWORD. MCP: create_database generates a password that it never returns. Create the application first, then pass connect_to_application_id and env_var_name: "DATABASE_URL": the tool connects the database and stores its URL, in the form postgresql://<user>:<password>@<host>:<port>/<database>, which Hanami accepts like postgres://. Then skip the connection step, and leave the connection’s variables out of the environment variables step.4
Create the application
Create application (Sevalla adds the domain a few seconds after it creates the application, so the loop waits for it.CLI:
createApplicationV3) creates it with a web process and doesn’t deploy it. List application domains (listApplicationDomainsV3) returns its sevalla.app domain as the primary one, for the checks:sevalla apps create --name storefront --cluster $CLUSTER_ID --source privateGit --git-type github --repository $REPO_URL --branch $BRANCH, then sevalla apps domains list --app-id $APP_ID. MCP: create_application with deploy: false, then get_application.5
Size the web process and add the readiness probe
The API creates the web process at S1, not the dashboard’s H1. List processes (CLI:
listProcessesV3) finds it, and Update process (updateProcessV3) sets H1 and the readiness probe on /health. Send timeoutSeconds: a probe set through the API without it waits 120 seconds, not the dashboard’s 1:sevalla apps processes update $WEB_ID --app-id $APP_ID --resource-type $H1_ID; the CLI has no option for the probe. MCP: scale_process with size_id and apply_now: false for the size, and sevalla_api_update with updateProcessV3 and the same body for the probe.6
Connect the database
Create internal connection (It prints the connection’s ID. If it prints nothing or
createApplicationInternalConnectionV3):null, the connection wasn’t created: run the call again, because without it the application can’t reach the database. Unlike the dashboard, the API doesn’t add the connection’s environment variables. The next step adds them.CLI: sevalla apps internal-connections create $APP_ID --target-id $DB_ID --target-type database. MCP: sevalla_api_create with createApplicationInternalConnectionV3 and the same body.7
Add the environment variables
Create environment variable (CLI:
createEnvironmentVariableV3) adds one variable per call. The loop adds the connection’s variables in the dashboard’s names and format, from Get database, with DB_URL renamed to DATABASE_URL, then HANAMI_SERVE_ASSETS, all for runtime only:sevalla apps env-vars create $APP_ID --key HANAMI_SERVE_ASSETS --value true, once per variable; the CLI makes each variable available during build and runtime, with no option for runtime only. MCP: set_environment_variables with runtime: true and buildtime: false for each variable.8
Create the migration job
Create process (CLI:
createProcessV3) needs the size, a scaling_strategy and, for a job, its job_start_policy:sevalla apps processes create $APP_ID --name Migrate --type job --resource-type $H1_ID --command "bundle exec hanami db migrate --no-dump" --job-start-policy beforeDeployment. MCP: sevalla_api_create with createProcessV3 and the same body.9
Deploy
Trigger deployment (CLI:
triggerDeploymentV3):sevalla apps deployments trigger $APP_ID --branch $BRANCH. MCP: trigger_deployment.10
Wait for the deployment
Poll Get deployment (On
getDeploymentV3) until the status is final: success, failed, cancelled or skipped. The loop keeps polling through a failed request and stops after 30 minutes:failed, read the whole build log with Get application deployment logs (getApplicationDeploymentLogsV3), curl -s "$API/applications/$APP_ID/deployments/$DEPLOYMENT_ID/logs?limit=5000" -H "$H" | jq -r '.[].message', and see Troubleshoot. CLI: sevalla apps deployments get $DEPLOYMENT_ID --app-id $APP_ID and sevalla apps deployments logs $DEPLOYMENT_ID --app-id $APP_ID. MCP: get_deployment and get_deployment_logs.11
Turn on auto-deploy
Update application (To build from the Dockerfile instead of Ingot, send
updateApplicationV3):{"build_type": "dockerfile", "dockerfile_path": "Dockerfile", "docker_context": "."} with the same call before you deploy. CLI: sevalla apps update $APP_ID --data '{"auto_deploy": true}'. MCP: sevalla_api_update with updateApplicationV3 and the same body.https://$APP_HOST as the domain.